

Your last manual pentest was three months ago. Your codebase has changed a couple of hundred times since. That $25,000 security report validated a system that no longer exists.
Meanwhile the threat has shifted under it. In the Verizon 2025 Data Breach Investigations Report, exploitation of vulnerabilities rose to 20% of breaches as an initial access vector, a 34% jump year over year, now sitting just behind stolen credentials. Attackers are not only phishing your employees. They are exploiting the logic flaws in the code you shipped last Tuesday.
Automated penetration testing has gone from niche experiment to engineering standard because the gap between quarterly manual testing and weekly deployments became impossible to ignore. This guide breaks down the technical, business, and compliance drivers behind the shift, walks through the black, gray, and white box workflow, and is honest about where automation wins and where human expertise still matters.
Why Automated Pentesting Is Replacing Point-in-Time Manual Testing
The math does not work. A team shipping 50 or more releases a year budgets for two to four manual pentests at $15k to $50k each. If your last test was eight weeks ago and your codebase changed 200-plus times since, every merged PR, dependency bump, and infrastructure change has widened the attack surface that the report never saw.
Approach | Annual cost | Test frequency | Coverage |
|---|---|---|---|
Manual pentesting | $60k to $200k | 2 to 4 times a year | 90 to 180 days stale |
Automated pentesting | $30k to $80k | Continuous | Real-time validation |
Hybrid (recommended) | $50k to $120k | Continuous plus annual | Best of both |
This is not about replacing skilled pentesters. It is about matching testing cadence to deployment velocity. Automated pentesting provides continuous validation between manual engagements, catching regressions as they land rather than months later. We make the full case for cadence in Continuous vs Annual Penetration Testing.
What automated pentesting actually means
In 2026, automated pentesting means continuous, exploit-validation-oriented testing that confirms exploitability with a working proof-of-concept. It is distinct from vulnerability scanning because it proves a vulnerability is exploitable, not just theoretically present.
The security testing spectrum runs from detection to proof.
Vulnerability scanning (Qualys, Tenable) identifies known CVEs by signature match. It answers "what vulnerabilities exist?" without validating exploitability.
DAST (Acunetix, Invicti) probes apps with payloads to trigger responses. It tests for SQL injection, XSS, and CSRF but cannot understand business logic or trace data flows.
External attack surface management (CyCognito, Detectify) continuously discovers public exposure: subdomains, services, misconfigurations. These are reconnaissance platforms, not exploitation engines.
Autonomous pentesting combines reconnaissance, exploit validation, and attack-chain construction across black box, gray box, and white box modes, and delivers working exploits with curl PoC commands.
The question that separates the categories is simple: can you show me a working exploit? Theoretical findings create alert fatigue. Confirmed exploitability means the platform constructs a real attack, chains issues together, provides the curl command, and quantifies impact with evidence.
Black Box vs Gray Box vs White Box: The Workflow
The testing mode decides what intelligence the platform gets to use, and each mode fits a different point in the delivery cycle. We cover the concepts in depth in Black Box vs White Box vs Gray Box Penetration Testing. Here is how the workflow runs in practice, with the output each mode produces.
Testing mode | Code access | Example finding |
|---|---|---|
Black box | None | Exposed admin panel at |
Gray box | Partial (key files) | Broken Object Level Authorization in a GraphQL resolver letting user A read user B's orders |
White box | Full repository | JWT validation bypass in custom middleware enabling privilege escalation |
Black box: start where the attacker starts
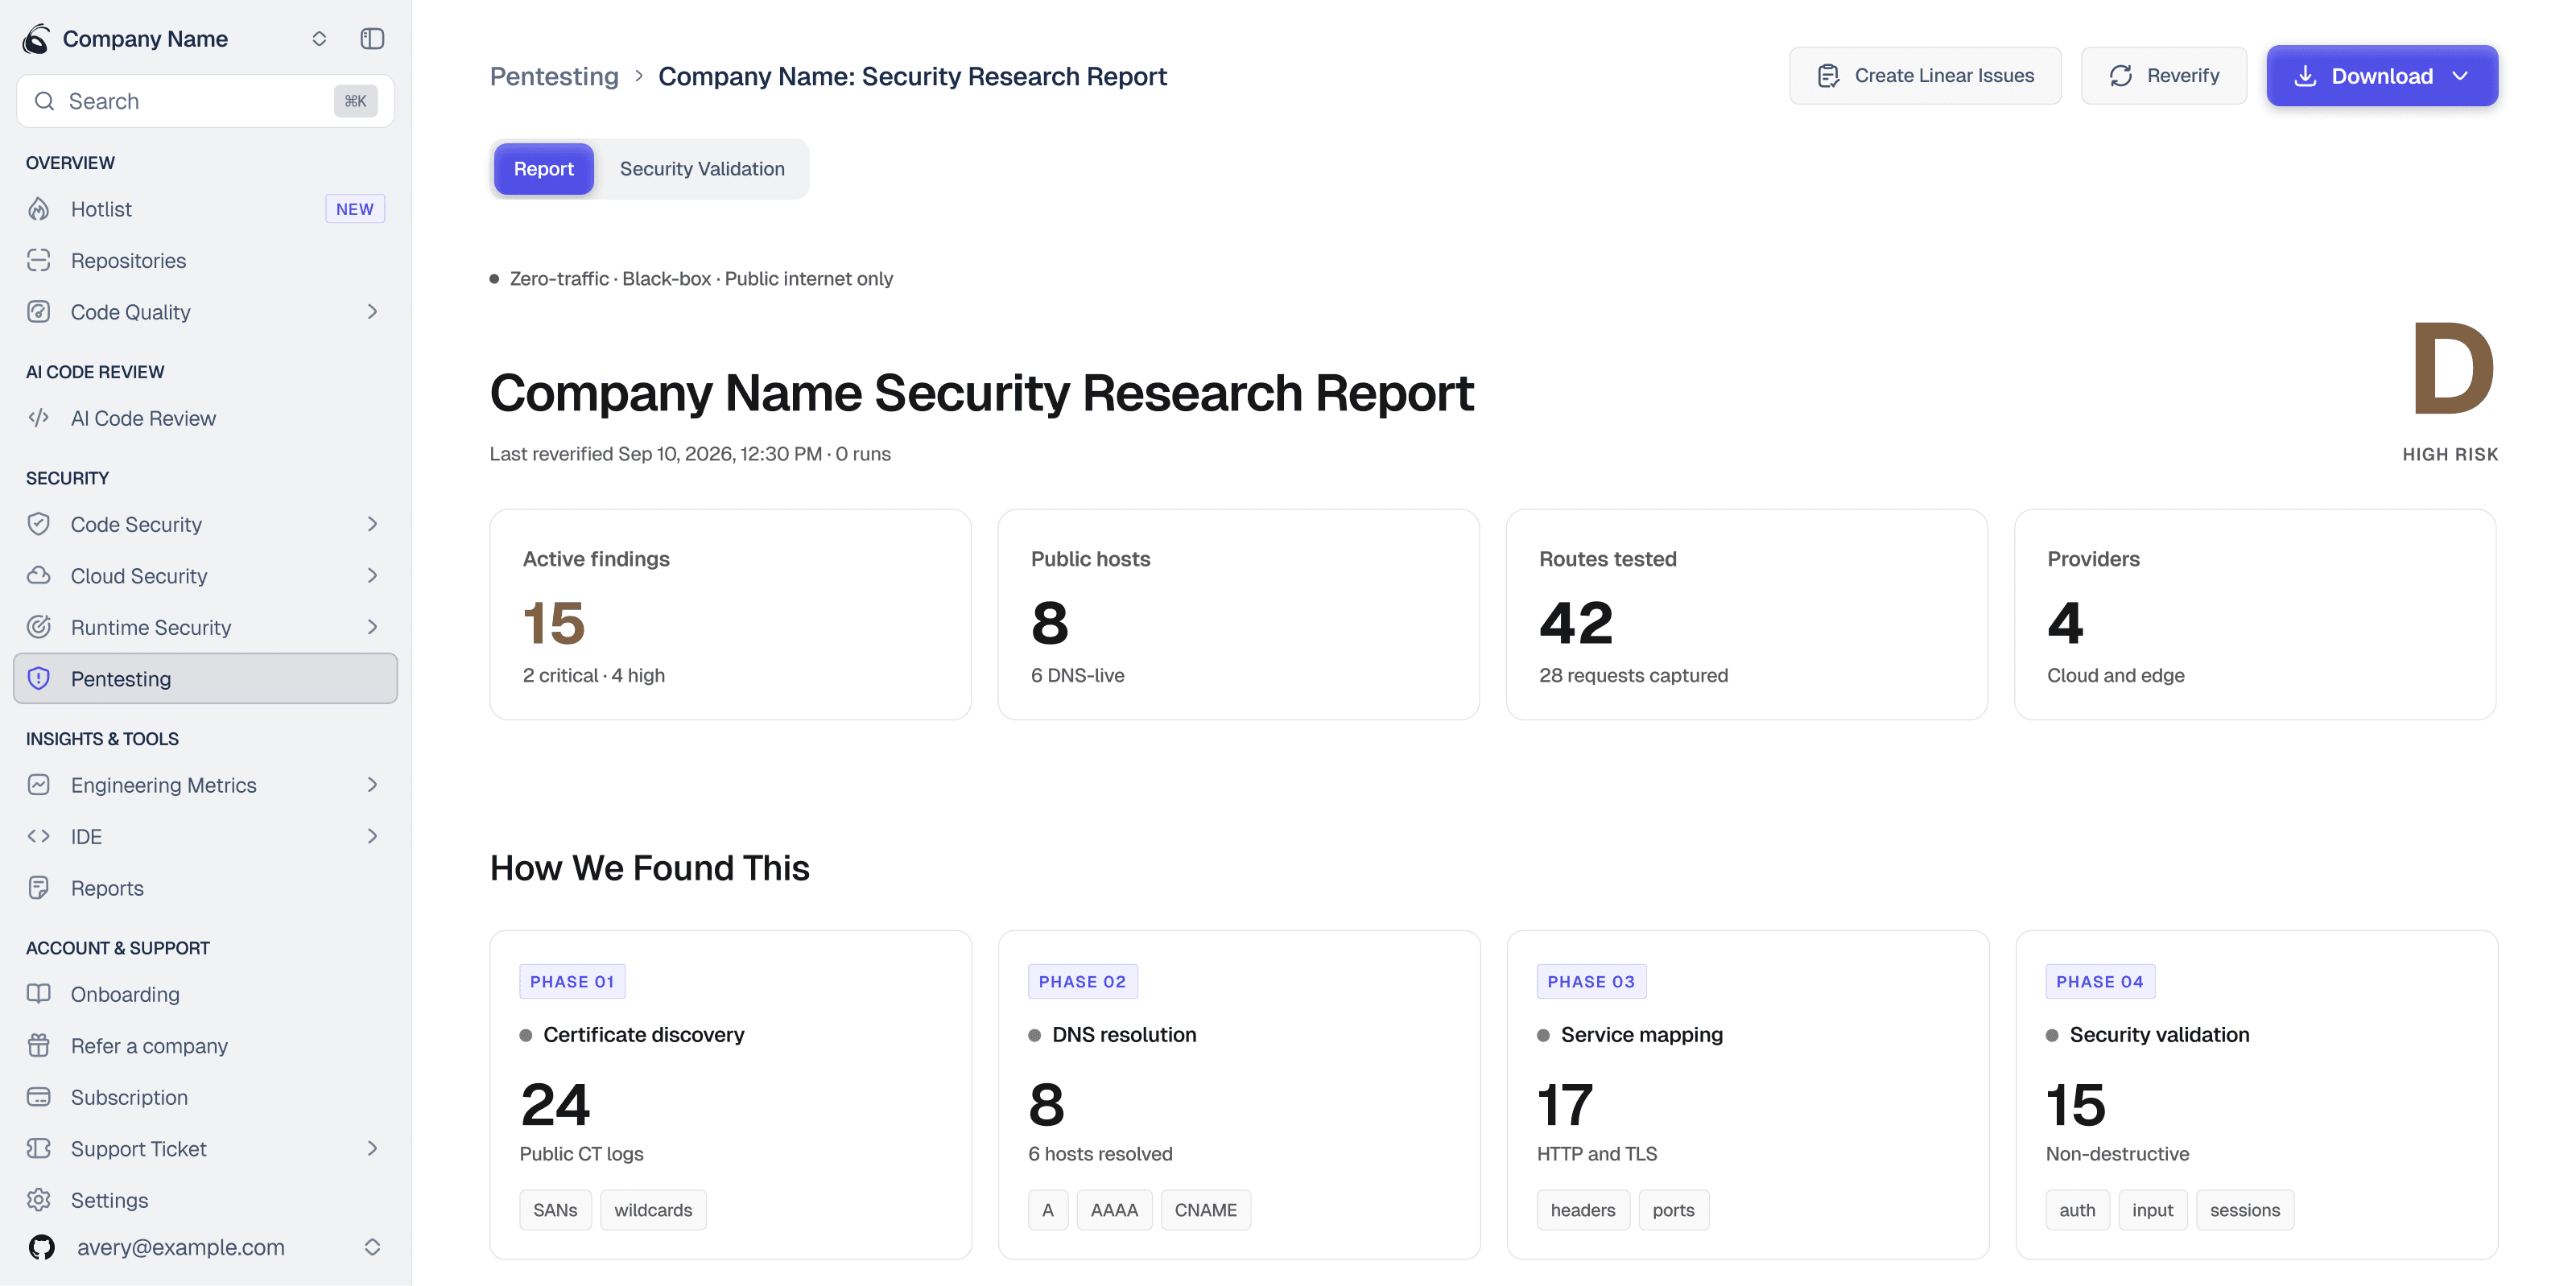
Black box testing approaches the system as an external attacker would, with no credentials and no code access. It answers one question: what can an unauthenticated attacker discover and exploit?
The workflow runs reconnaissance first, subdomain enumeration, JavaScript bundle analysis, service discovery, then probes what it finds. It is the right baseline for a compliance run and for catching the exposures that never should have shipped, like a forgotten admin panel or a secret hardcoded in a client-side bundle.
Gray box: attack from outside with inside knowledge
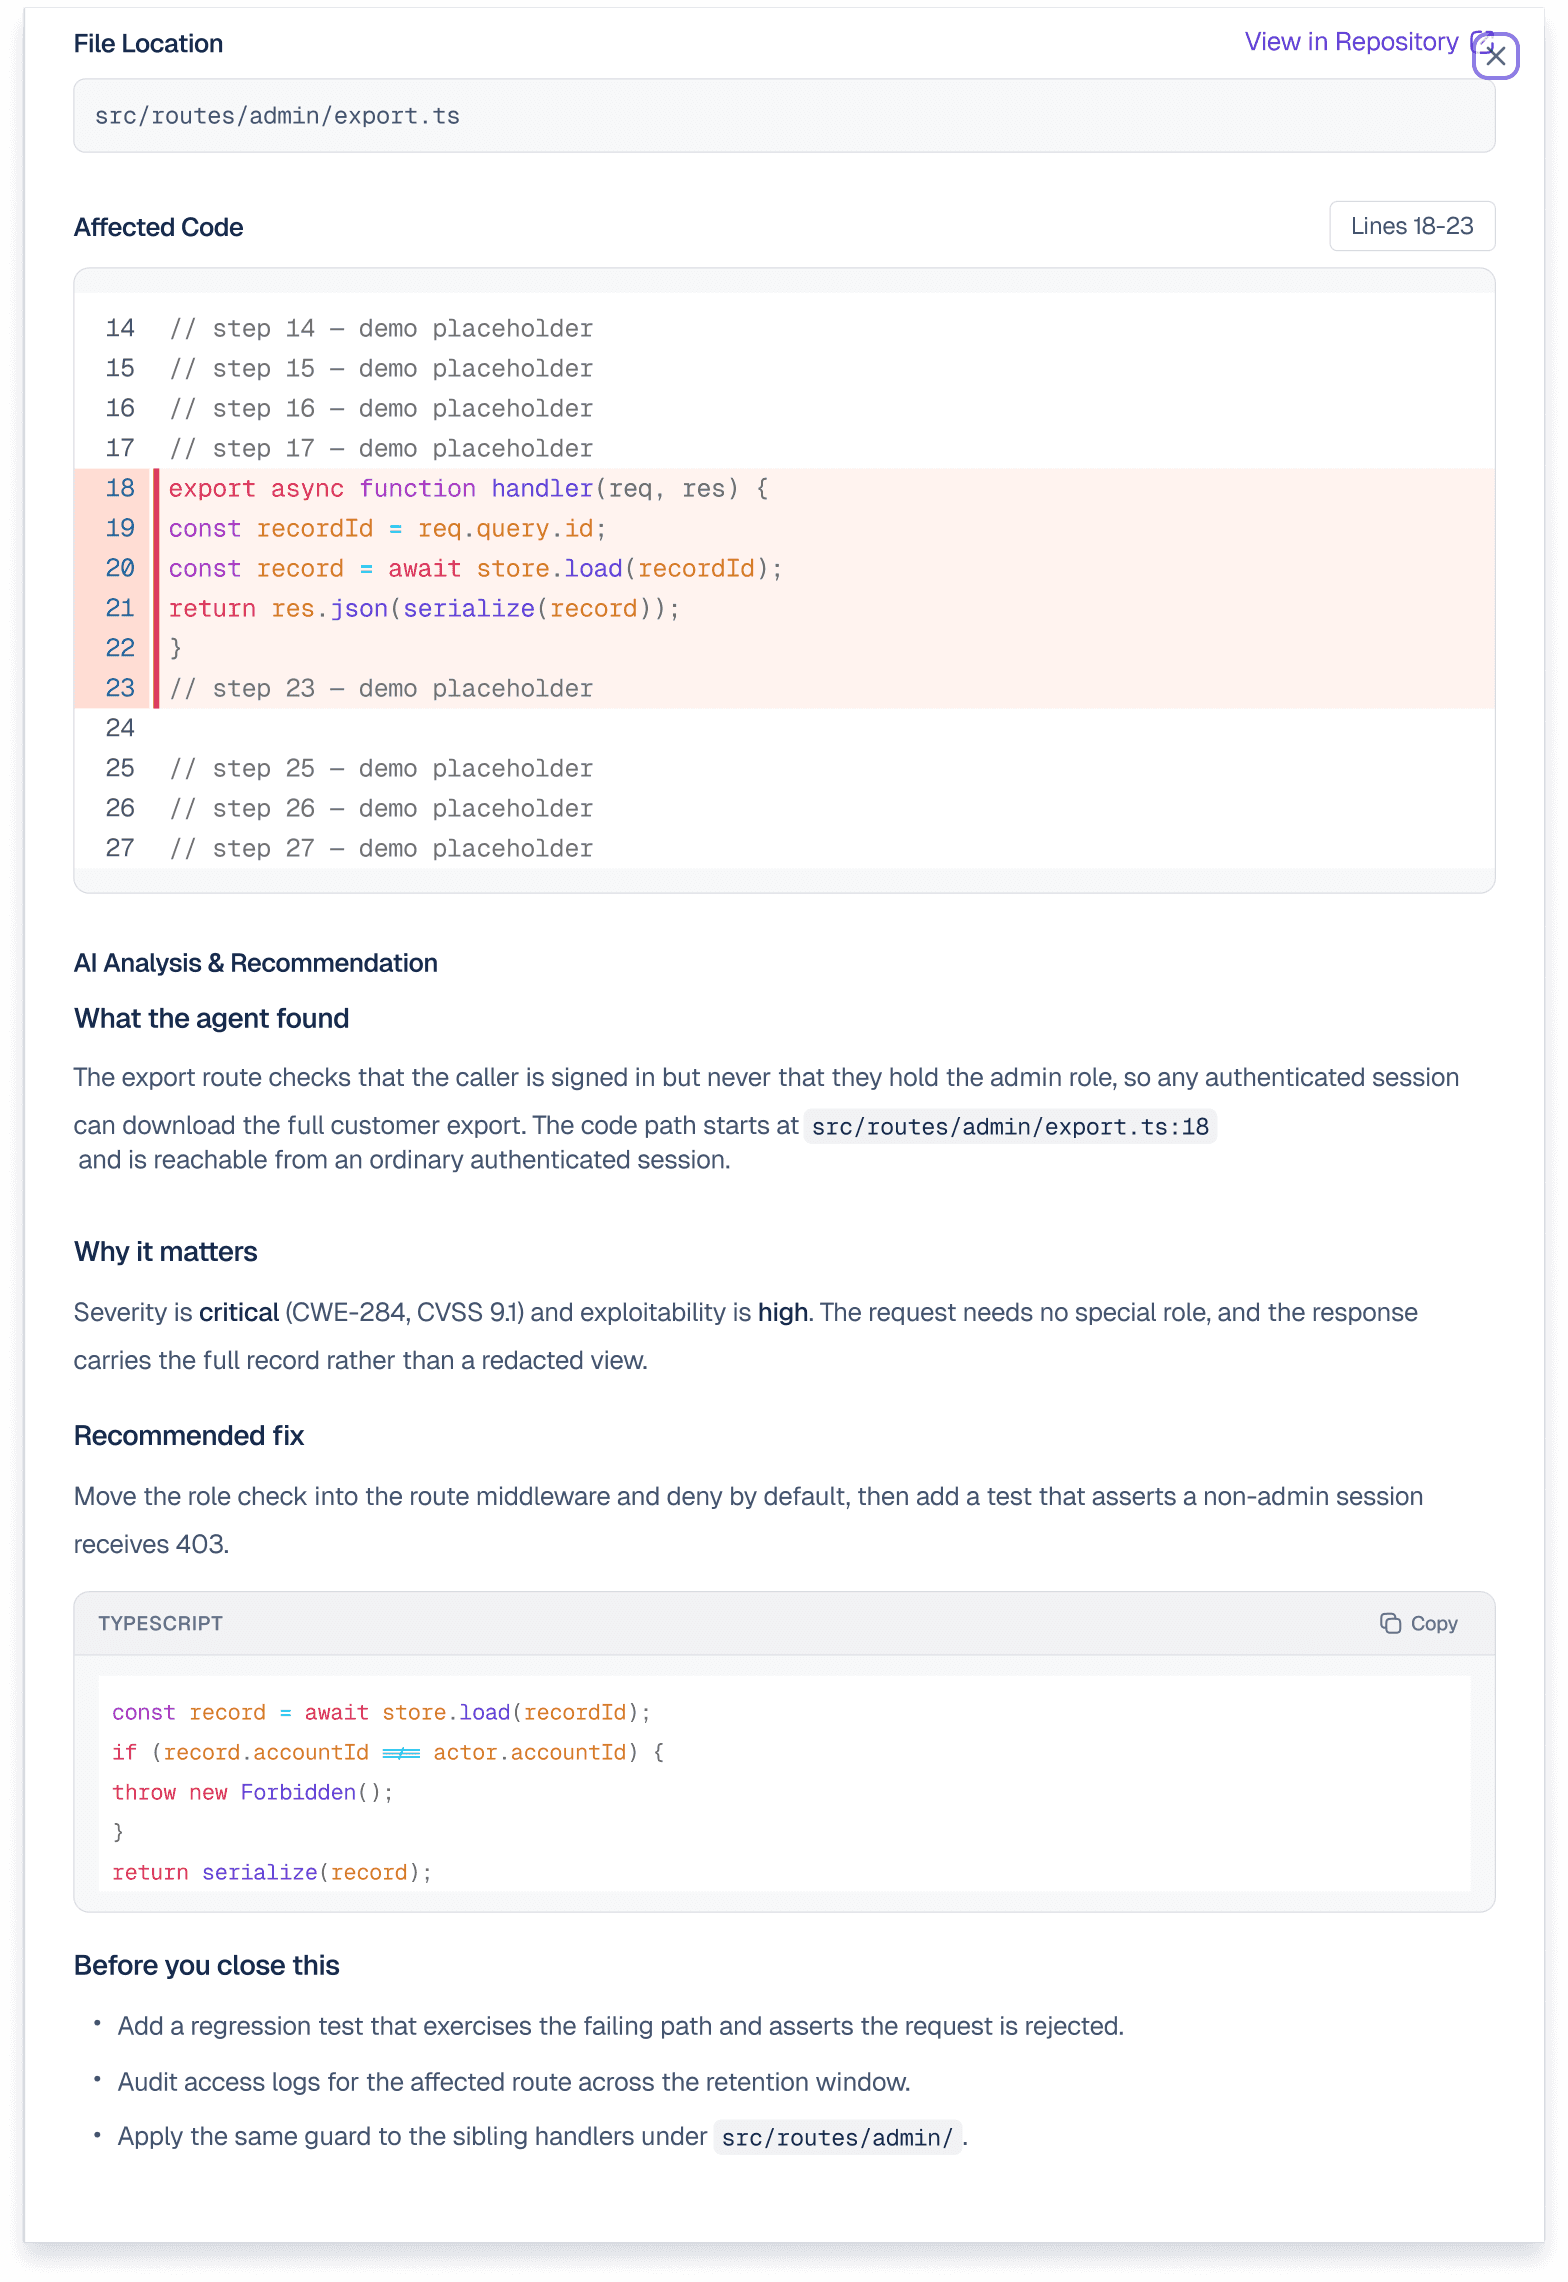
Gray box is the mode most modern autonomous platforms run, and it is where code-aware testing pulls ahead. The system has partial knowledge, typically authenticated access plus key code intelligence, so it can test authenticated flows and validate authorization boundaries without needing full architecture docs.
This is where the vulnerabilities that actually cause breaches live: Broken Object Level Authorization and IDOR, privilege escalation, tenant-boundary bypass. Because the platform already knows where authentication exclusions are defined, it does not waste cycles testing routes that are properly guarded, it goes straight for the ones that are not.
White box: full-repository depth before a release
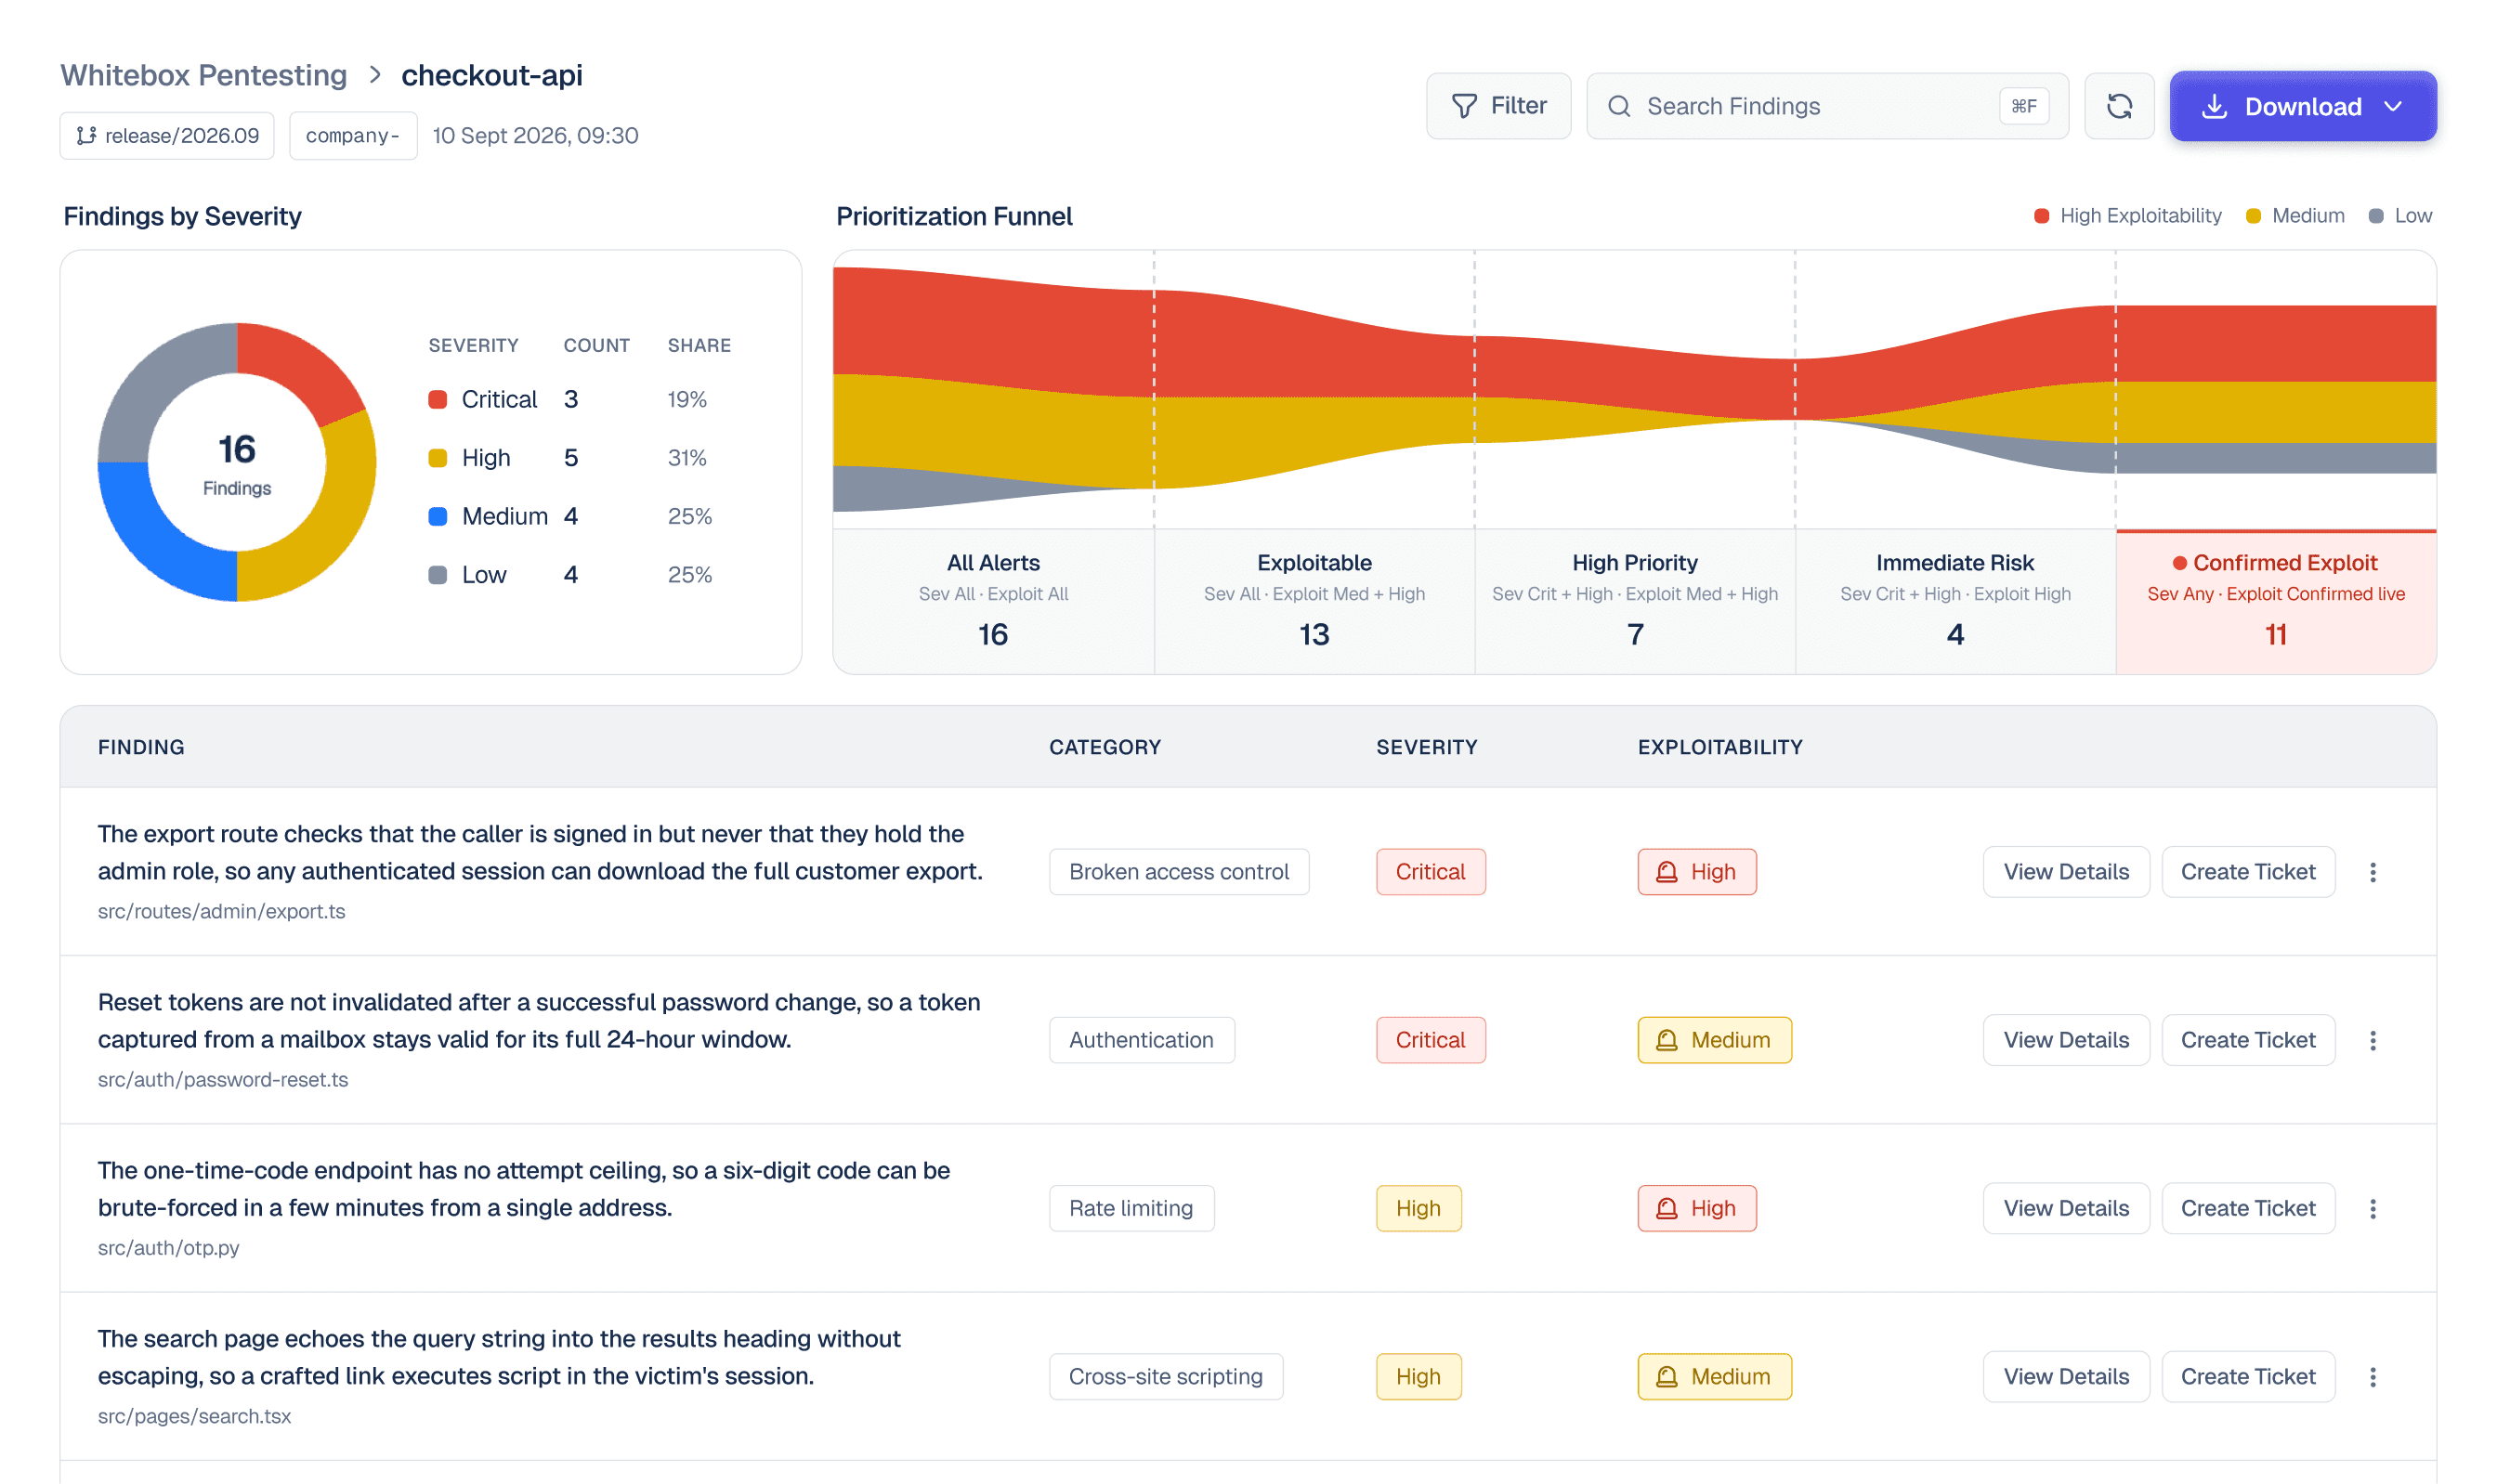
White box testing has full source access, architecture, and internal docs. The platform reads authentication middleware end to end, traces data flows from request to sink, understands role boundaries, and tests business logic with complete context. It is the mode for pre-release validation and for the deep exploit chains that need to see the whole codebase, a JWT validation bypass buried in custom middleware, or a resolver that skips field-level authorization.
The point of the three modes is not to pick one. It is to run black box continuously for baseline exposure, gray box continuously for the authorization flaws that matter most, and white box before major releases for depth.
Five Forces Driving Automated Pentesting Adoption
1. Software vulnerabilities became a top attack vector
Exploitation of vulnerabilities reached 20% of breaches in the Verizon 2025 DBIR, a 34% year-over-year increase, closing in on credential abuse at 22%. Attackers are shifting from unpredictable phishing to programmatic exploitation of the code you ship, and the reason is arithmetic.
One exploitable Broken Object Level Authorization flaw in your API lets an attacker enumerate and exfiltrate data across your entire user base with plain HTTP requests. One phishing email compromises one account. One software vulnerability can compromise millions of records.
First-generation automated platforms excel at infrastructure reconnaissance but struggle with application-layer flaws. They can discover an API endpoint but cannot reason about which middleware should protect it, what role checks should apply, how data flows from validation through business logic, or which GraphQL resolvers enforce field-level authorization.
A real finding. CodeAnt AI discovered a GraphQL Broken Object Level Authorization vulnerability that exposed 742 million person records. The platform traced the data flow from the resolver through the database query layer, identified the missing field-level authorization, constructed an exploit chain that enumerated user IDs, and delivered a curl PoC demonstrating full exfiltration, inside 48 hours.
2. Code-aware testing closes the application logic gap
Code-aware pentesting combines external adversarial reconnaissance with internal code intelligence. When the platform understands your codebase, it runs true gray box, attacking from outside while understanding the internal architecture defending against those attacks.
CodeAnt's defensive-offensive integration is the mechanism: the same platform reviewing your pull requests conducts the reconnaissance, so when the offensive engine finds an exposed endpoint it already knows which middleware is configured, where role checks are missing, and which resolvers enforce authorization.
A real finding. In one engagement CodeAnt identified middleware bypass vulnerabilities affecting 476,000 healthcare records. It did not just find the exposed endpoint. It understood from code analysis why the authorization middleware was not being enforced, and gave file-and-line remediation.
Vulnerability type | Needs code intelligence | External-only detection |
|---|---|---|
Broken Object Level Authorization / IDOR | Yes, must understand authorization logic | Limited, tests endpoints but cannot reason about access control |
JWT validation bypass | Yes, must trace token verification through middleware | Sees tokens as opaque strings |
GraphQL field-level auth | Yes, must analyze resolver-level permissions | Treats GraphQL as one endpoint |
Business logic flaws | Yes, must understand intended vs actual behavior | Cannot infer business rules |
3. AI-augmented attacks demand AI-powered defense
Attackers now use AI at every step. IBM's Cost of a Data Breach 2025 found that one in six breaches involved attackers using AI, typically to scale phishing and social engineering. On the offensive-tooling side, AI parses minified JS bundles to extract API endpoints in seconds (CodeAnt found 27,255 CRM contact records exposed in client-side code this way), generates payload variants that evade WAF signatures, and reasons about multi-step chains automatically.
The validation gap is the point. A scanner reporting "this endpoint might be vulnerable to Broken Object Level Authorization" is not the same as proving an attacker can exfiltrate 742 million records through it. AI-powered automated pentesting matches adversary speed with attack-chain reasoning where each step is validated before advancing, code-aware gray box testing, and continuous exploit validation after every deployment.
4. Compliance requires evidence, not intentions
Auditors want timestamped proof that you tested, found exploitable issues, fixed them, and can reproduce the evidence on demand. Manual testing creates evidence gaps: a five-to-eleven-week turnaround, stale evidence by the time the report lands, skipped retesting because it costs another $5k to $15k, and inconsistent report formats that make compliance mapping manual work.
What the frameworks actually require:
SOC 2 Type II: testing aligned with releases or quarterly minimum, timestamped remediation tracking, control mapping (CC6.1, CC6.6, CC7.2). See the SOC 2 penetration testing requirements.
PCI DSS 4.0: testing after significant changes and annually, segmentation validation, authenticated testing with exploit validation. See the PCI DSS penetration testing requirements.
ISO 27001: reproducible methodology, CVSS scoring, evidence retention for three or more years.
HIPAA: PHI exposure validation, attack-chain documentation, proof of remediation.
Automated pentesting delivers 24-to-48-hour reports with CVSS 3.1 scoring, control-violation mapping, and curl PoC exploits. It uses a reproducible methodology that produces comparable results, validates remediation with a re-scan at no extra cost, and structures findings for each framework.
5. The economics shifted
The real cost is not the invoice. It is the triage load from theoretical findings, the exploits that appear between tests, and the $4.44 million average breach cost (IBM, 2025) when an attacker finds what quarterly testing missed. Manual testing hides costs: 15 to 20 hours triaging 40 to 80 findings per engagement, many flagged "informational" with no confirmed exploitability, and a $5k to $10k retest fee that discourages validating that a fix worked.
Exploit-first automation flips it. Only findings with a working PoC reach your team, reports carry curl commands mapped to files and lines, re-testing is unlimited, and one CodeAnt customer cut security triage from 18 hours per manual pentest to 3 hours per automated scan.
Where Manual Pentesting Still Wins
Automation excels at continuous validation and exploit confirmation at scale. Being honest about the boundary is what makes the rest credible: skilled human pentesters still win in four areas.
Complex business logic. Automated systems test known patterns. A human finds application-specific flaws like "users can stack discount codes to make an order free," which requires understanding business intent, not just technical implementation.
Novel zero-day discovery. Automation executes known techniques efficiently. Humans discover new attack classes through edge-case experimentation and creative abuse of intended functionality.
Social engineering and physical security. Automated testing lives entirely in the technical domain. Human engagements test phishing susceptibility and physical vectors no automated system replicates.
Advanced evasion and red team operations. Sophisticated adversaries use custom tooling, timing-based evasion, and multi-stage persistence. Manual red team exercises simulate advanced persistent threats in ways platforms built for speed and breadth cannot.
The winning strategy is a cadence, not a single choice.
Testing type | Frequency | Purpose |
|---|---|---|
Automated pentesting | Continuous, post-deployment | Regression testing, known-pattern validation, compliance evidence |
Manual pentesting | Annual or major releases | Novel vulnerability discovery, business logic, threat modeling |
Red team | Bi-annual or as needed | APT simulation, evasion, detection and response validation |
Implementation Playbook
Define your attack surface scope
Prioritize by risk, not by inventory. Start with the internet-facing applications (public APIs, customer portals, auth flows), the authenticated flows (post-login business logic, RBAC boundaries, data export), and the critical APIs (payment, PII handling, GraphQL). A useful rule of thumb: the 8 or so services handling authentication, billing, and customer data are often a small slice of the codebase but the large majority of business risk.
Choose the testing mode per goal
Mode | What the platform sees | Best for |
|---|---|---|
Black box | External behavior only | Initial discovery, compliance baseline |
Gray box | Authenticated access plus repo analysis | Continuous validation, Broken Object Level Authorization and IDOR detection |
White box | Full source and architecture | Pre-release validation, deep exploit chains |
Set SLAs for findings
Severity | Criteria | Response SLA | Remediation SLA |
|---|---|---|---|
Critical | Working PoC plus PII or financial exposure | 4 hours | 24 hours |
High | Authenticated exploit chain plus logic bypass | 24 hours | 72 hours |
Medium | Theoretical vulnerability, limited scope | 1 week | 2 weeks |
Build the retest loop
The loop is what makes continuous testing real. A developer fixes the vulnerability and commits with the finding ID. CI/CD triggers a targeted retest. The platform re-runs the exploit chain against the fixed endpoint. The finding auto-closes if the exploit now fails, with a timestamp and commit hash, or reopens with evidence if the fix was incomplete.
Measure outcomes
Track mean time to remediation (target under 72 hours for critical findings), the ratio of exploit-confirmed to theoretical findings (higher means less noise), the regression rate of fixed findings that reappear (target under 5%), and coverage expansion across endpoints and authenticated flows.
Stop Validating a System That No Longer Exists
The shift from the quarterly report to continuous validation is a response to how teams actually ship. Release velocity outpaced testing, software vulnerabilities became a top breach vector, external-only tools miss application logic, AI-augmented attacks move faster than any human engagement, and auditors want timestamped proof, not intentions.
That is what CodeAnt AI is built for. It runs all three modes, black box for external exposure, gray box for the authorization flaws that cause real breaches, white box for pre-release depth, from one code-aware engine. Because the same intelligence that reviews your pull requests drives the offensive testing, it already knows where your authentication logic lives before the first probe. It confirms every finding with a working PoC, maps it to the exact file and line, and re-scans unlimited times after each fix. Low and medium findings are free, and you pay only when a high or critical is confirmed exploitable.
Where to start this week
Measure your cadence gap: count how many times your codebase changed since your last security validation. If the answer is more than a handful, pick your single highest-risk application, the one touching payments or PII, and run a gray-box scan against it. Require proof, a working PoC with a curl command mapped to a file and line, not a theoretical finding. Then wire the retest loop so every fix is validated before it ships.
Run a free code-aware pentest →
Related reading
Black Box vs White Box vs Gray Box Penetration Testing: the three modes in depth, and which fits each part of your stack
Continuous vs Annual Penetration Testing: why cadence, not depth, is the real differentiator
What Is VAPT? Vulnerability Assessment vs Penetration Testing: the scanning-vs-testing distinction this article builds on
CVSS, EPSS, and CISA KEV: How to Actually Prioritize Vulnerabilities: turning a pile of findings into a triage order
IDOR Vulnerabilities: The Complete Technical Guide: the authorization flaw class gray box testing is built to catch

